1. Why a website does not appear in search: causes 1–2
A common situation for business owners: the website is built, the domain is connected, and pages open in a browser, but the company cannot be found through Google or Yandex. Sometimes the whole site is missing; sometimes only certain services, articles, or product pages are absent.
The first reaction is often to look for a way to submit the site urgently. Start with diagnosis instead. A page may be missing because of technical restrictions, server errors, duplicates, content that offers too little value, or simply because a search engine has not processed the new URL yet.
Distinguish discovery, crawling, indexing, and ranking. Discovery means the search engine knows a page's address. A crawler may then request its content. After processing, the search engine decides whether to include it in the index. An indexed page is not guaranteed a high position for every query. A site missing from the top ten and a site absent from the index are different problems.
Use Google's URL Inspection and indexing reports in Search Console. For Yandex, check Yandex Webmaster's indexing, pages in search, excluded URLs, and server response information. The `site:` search operator may offer a rough view, but it does not replace owner tools.
Cause 1: the site is new and has not been discovered yet. Search engines find URLs through links, sitemaps, and other signals; discovery may take time, especially when a new site has few links and its sitemap has not been processed. Check that the permanent URL works, returns the right HTTP response, appears in the XML sitemap, and is known to webmaster tools. Make sure crawling is allowed, the site has working links, submit the sitemap, and request inspection of an important URL if appropriate. Repeated submission does not guarantee indexing or fix technical issues.
Cause 2: few internal links point to the page. A new WordPress service may be published but missing from the service catalogue, menu, homepage cards, and related articles. A sitemap may still help search engines discover it, but a lack of meaningful links makes it harder to crawl and understand the page's place in the site. Check that normal HTML links lead to it without errors or incorrect redirects, and add relevant links from the catalogue or related content. Avoid adding hundreds of identical links; clear structure and useful paths matter more.
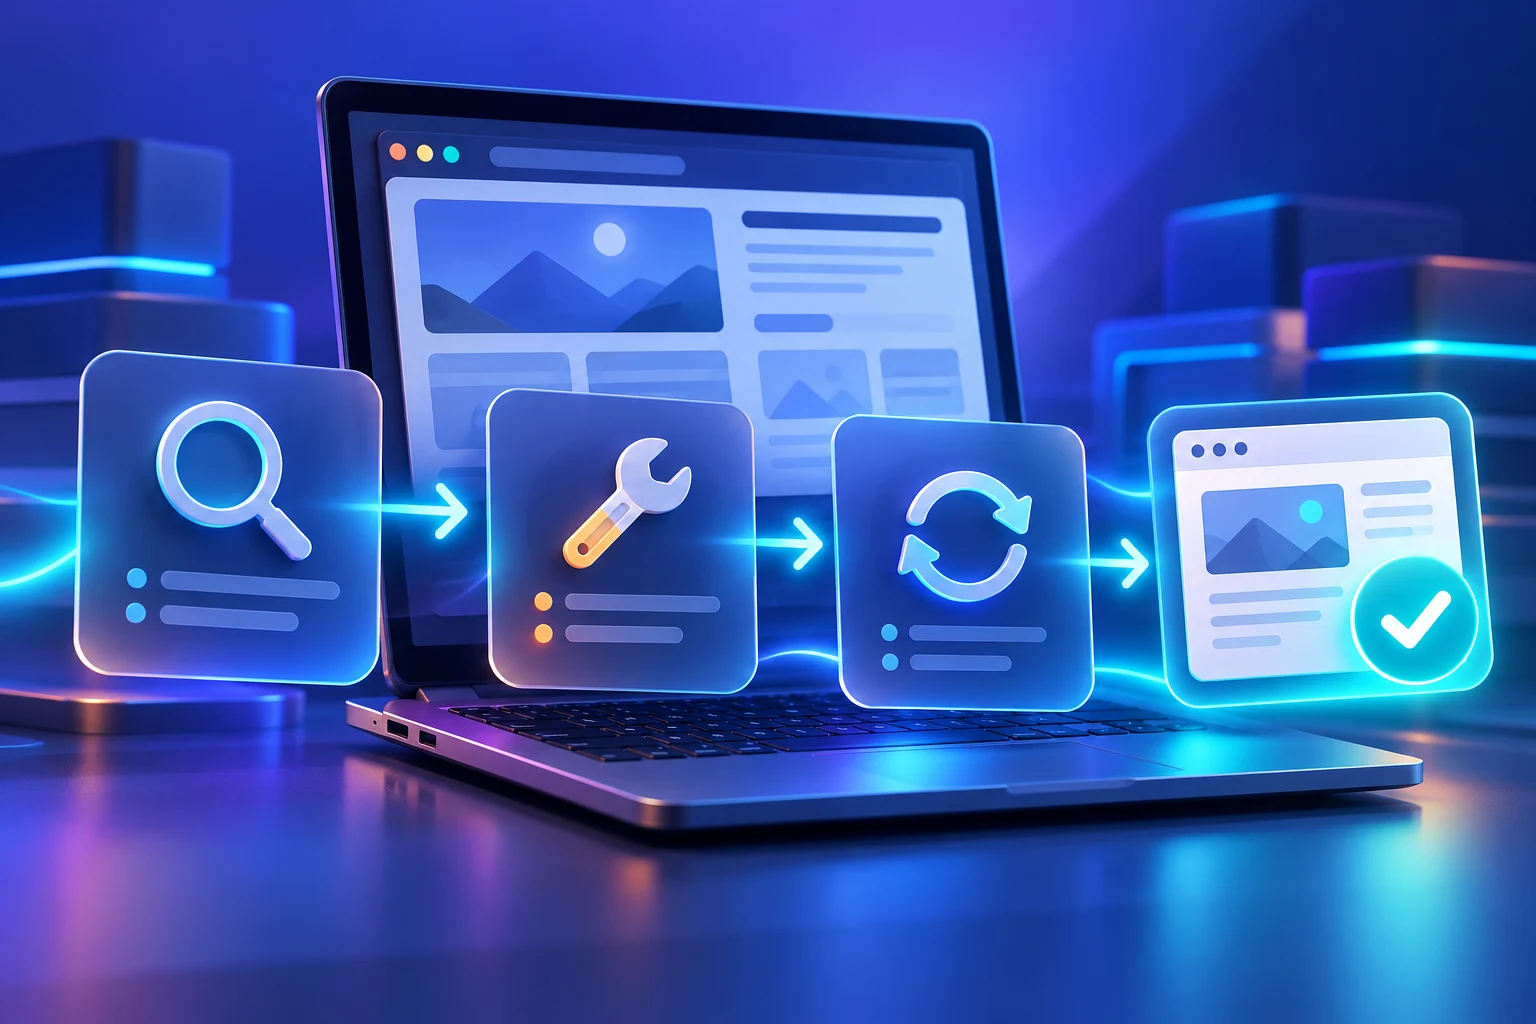
First identify where the process breaks down: discovery, crawling, indexing, or ranking. The right fix depends on the stage causing the problem.
2. Robots.txt and noindex: causes 3–4
Cause 3: robots.txt blocks the crawler. This file sets crawling rules for search bots and is often used to limit access to technical areas or URLs that do not need to be crawled. A mistaken directive can also block important pages. For example, a site may have blocked crawling during development and the restriction may remain after launch. Visitors can see a page while a crawler is not allowed to request it.
Open robots.txt on the live domain and review the rules for each relevant user agent. Googlebot and Yandex rules may differ; check both the `User-agent` and the path affected by `Disallow`. Remove only restrictions that incorrectly block pages intended for search. Keep appropriate protection for private accounts and technical areas.
Blocking crawling in robots.txt is different from a noindex directive. A blocked URL may still be known to a search engine through external links, even if its content cannot be crawled. If the goal is to control indexing, use a mechanism the search engine supports and make sure the crawler can access it.
Cause 4: the page has noindex. This directive tells a supporting search engine not to include a page in its index. It can appear in a robots meta tag or the `X-Robots-Tag` HTTP header. Noindex can be useful for private pages or some duplicates, but an accidental directive on the homepage, services, or articles can prevent them from appearing. In WordPress, check site visibility settings, Yoast SEO, and settings on the individual post or post type.
Review the live HTML and HTTP headers, and make sure the crawler can read the directive. Remove accidental noindex only from pages meant to be indexed; do not enable index everywhere, since the number of indexed pages is not a measure of SEO quality. After changing settings, check the published page, because caching may continue to serve an older version. Robots.txt and noindex must be diagnosed separately: both can affect search visibility, but they work differently.
3. Server errors and canonical tags: causes 5–6
Cause 5: the server returns an error instead of page content. A crawler needs an appropriate server response. A 404 means the resource was not found, a 403 means access was denied, and 5xx errors indicate a server or related processing problem. A page may open in the owner's browser while a bot receives a different response because of security settings, server rules, or a CDN. This matters on sites using a WAF, anti-bot checks, or request limits.
Check the URL's actual HTTP status, redirects, server logs, crawl information, and webmaster-tool inspection results. Confirm that a crawler receives the content available to a regular visitor. Restore access and fix server errors or security rules that block legitimate crawling, but do not disable site security altogether. For temporary downtime, return the appropriate status rather than an error page with a 200 response.
Cause 6: incorrect redirects or canonical tags. A page may be available under several URLs, such as www and non-www, HTTP and HTTPS, with or without a trailing slash, or with query parameters. Search engines try to identify a primary version. `rel=canonical` is a signal, not an unconditional command; if it points elsewhere, the search engine may select that other URL. A redirect may also take visitors to an unintended address.
Check the final URL after redirects, each response in the chain, the canonical in the HTML, and the canonical reported in Search Console. Make sure the sitemap and internal links do not list conflicting versions. Choose the preferred URL and keep internal links, sitemap, redirects, and canonical tags consistent. Do not change canonicals in bulk without diagnosing the cause: an incorrect change can remove valuable pages. If Google selects a different canonical, first establish whether the pages are duplicates and which URL should represent the content.
What to check when a site is not indexed
- Google Search Console — inspect the URL and its exclusion reason
- Yandex Webmaster — review pages in search, excluded URLs, and crawl results
- HTTP response — confirm the URL is accessible and returns the right status
- robots.txt — check that the relevant crawler is not blocked
- noindex — inspect page directives and HTTP headers
- Canonical and redirects — confirm the primary URL and redirect destination
- Internal links — ensure the page is reachable from relevant sections
- XML sitemap — check that it is available and lists the correct URLs
4. Duplicate content and weak internal links: causes 7–8
Cause 7: the page offers too little unique value or duplicates another page. Search engines may choose not to index every URL, particularly if several pages contain nearly identical information or a page does not adequately answer a user's query. Review whether the content is genuinely useful and distinct, not just whether it contains a target phrase. Improve pages that lack substance and keep technical pages out of the index when they are not meant for search. Do not add thousands of words simply to make a page longer. A commercial page should explain its offer, terms, process, and contact options; an informational article should answer the reader's question.
Cause 8: important pages lack clear internal links. Internal links help search engines discover URLs and understand how sections relate. A services catalogue can link to pages for web development, SEO, social media, and paid search, while related articles can link to relevant services. Sometimes a new page exists only in WordPress and the sitemap, with no path from the main navigation.
Check links from the homepage, catalogue, categories, and related content, and confirm they work and point to current addresses. Review whether visitors can move from general sections to a specific service, between related articles, or from a case study to the relevant service. Add natural links where useful, such as from an article about website types to a web development service. Avoid repeating the same commercial links in every paragraph. Check mobile navigation as well. Internal links should help visitors first and help search engines understand the site second.
5. JavaScript and XML sitemaps: causes 9–10
Cause 9: important content depends on JavaScript that is not processed correctly. JavaScript itself does not prevent indexing, and Google can render many JavaScript pages. Problems arise when important text and links appear only after user actions, scripts fail, or the server returns an incomplete document. A visitor may see a full catalogue after scripts run while a crawler receives incomplete content because a script or data request failed.
Check the source HTML, rendered page, JavaScript errors, resource availability, and whether the main text and links are visible. Search Console URL Inspection can show information available to Google and, for an accessible URL, let you test the published version. Source HTML and rendered HTML can differ. Make sure core content loads reliably and links use accessible URLs. Depending on the project, server-side rendering, pre-generated HTML, or improvements to client-side loading may help. You do not need to avoid JavaScript entirely. On WordPress sites using PHP templates and ACF, confirm that important headings and text appear in the final HTML and do not rely only on decorative scripts.
Cause 10: the XML sitemap is broken or contains incorrect URLs. A sitemap helps search engines learn about important URLs, especially on large or frequently updated sites, but it does not guarantee crawling or indexing. Problems include an unavailable file, outdated URLs, links to errors or redirects, technical pages, or pages blocked from indexing. After permalink changes, old addresses may remain; an SEO plugin may also include archives that should not appear in search.
Check that the XML sitemap is accessible, correctly structured, and contains current canonical URLs that agree with robots.txt, noindex, and redirects. For Yoast SEO, check its sitemap and which post types and taxonomies are included; the index is often `/sitemap_index.xml`, but verify the live installation. Remove incorrect URLs and include pages intended for indexing. You can then review the sitemap in Google Search Console and Yandex Webmaster. Repeated resubmission will not accelerate indexing, and technical URLs, filter archives, internal search results, and private pages do not belong in a sitemap. A good sitemap reflects the site's important content and agrees with its technical settings. A page can look and work normally while still presenting a crawler with incomplete information, so diagnosis must examine what search engines actually receive.
6. How to restore visibility in Google and Yandex: a step-by-step plan
If a site is missing from Google or Yandex, avoid changing every SEO setting at once. Identify the cause and check each fix in order.
1. Define the scope: is the entire site missing, or only some pages? If the homepage is indexed but new services are not, the issue may be limited to those URLs. If a page is indexed but does not appear for a competitive query, the problem may be ranking rather than indexing.
2. Inspect the URL in Google Search Console. Check whether Google knows the page, whether it can be indexed, and which canonical it selected. Review the crawl and indexing details, not just the status.
3. Check Yandex Webmaster's indexing and excluded-page reports. If a URL is excluded, identify the reason: a directive, server error, redirect, duplicate, or content quality.
4. Check the server. Confirm the URL returns the right response and is not blocked by security rules. If only a crawler is affected, review webmaster information and logs. Do not disable anti-bot protection without evidence that it is necessary.
5. Review robots.txt and noindex. Make sure pages intended for search can be crawled and have no accidental exclusion. Keep justified restrictions for technical or private content.
6. Check canonical tags and redirects. Choose the primary URL for each important page and make sure the sitemap, internal links, redirects, and canonical agree.
7. Review the content from a visitor's perspective. Does it answer a specific question? Is it distinct from other pages? Is the structure clear? Improve the useful information rather than adding text just to increase the word count.
8. Check internal links. Make sure new services and articles are linked from relevant sections and all links point to current URLs.
9. Review the XML sitemap for the right URLs, availability, and obvious errors.
10. Recheck the page after changes. If appropriate, request indexing or a recrawl in the search engine's tools, but this does not guarantee immediate inclusion. Search engines need time to crawl and process changes.
If a page remains outside the index after technical fixes, investigate its content, duplicates, links, and search-engine reports. Several factors may be involved. Take extra care after a migration, domain change, URL restructuring, or major WordPress update; verify redirects, canonicals, sitemaps, and access to key sections.
Indexing is a technical prerequisite for search promotion, not the same as SEO performance. To attract an audience, pages must also match user intent, be useful, and work well. Bravix helps companies with website health, structure, content, and SEO promotion. If you cannot identify why a site is not indexed, inspect specific URLs in webmaster tools and record the problems first. Then prepare a clear plan for technical fixes and further optimisation. There is no universal “submit to Google and Yandex” button: resolve the real issues that prevent search engines from discovering, processing, and showing important pages.
For ongoing checks, keep a record for important URLs: the address, check date, server response, status in Google Search Console and Yandex Webmaster, crawl permissions, selected canonical, and changes made. Note what you tested and when to check again. Changing several settings at once makes it harder to identify what affected the result. A log is especially useful after a migration, CMS update, or structural change, and helps compare results and hand technical work to a developer without losing context.